Research
I study how agents plan and act when their objectives conflict and some goals take priority over others. My work combines noncooperative game theory, numerical optimization, and optimal control, with applications to multi-agent systems.
Current work: receding-horizon control with ordered objectives
I develop efficient numerical methods to solve Games of Ordered Preference (GOOP) for real-time receding-horizon control. The examples below show preliminary results.
Highway overtaking
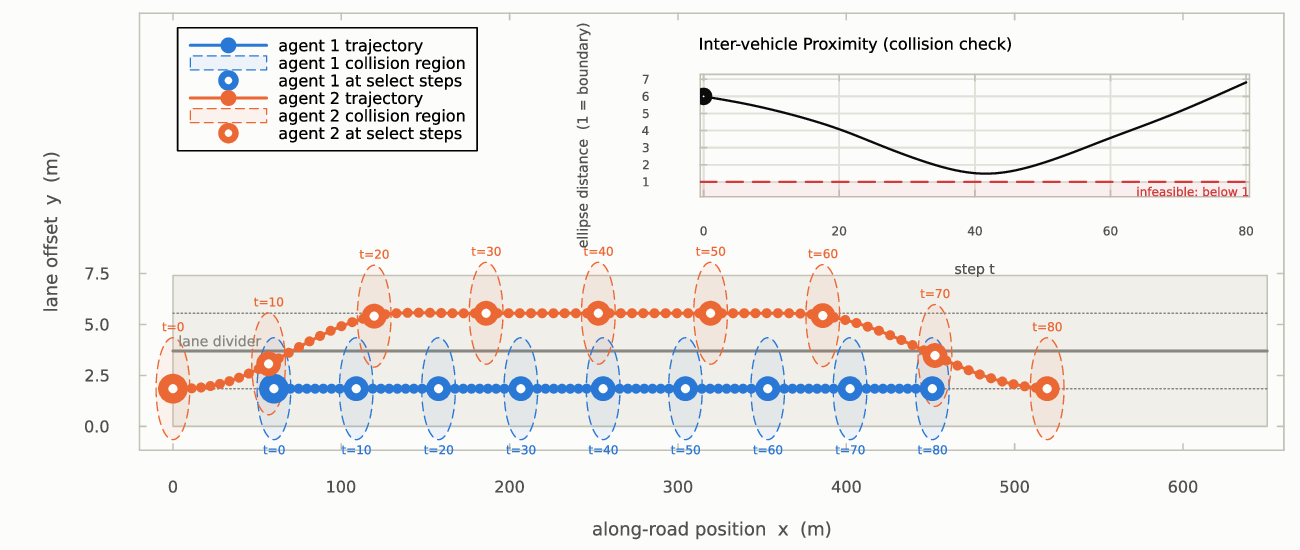
The ego vehicle (red) overtakes the blue vehicle while anticipating its behavior through a game-theoretic model. The compact reformulation and Newton solver reduce the computational burden, enabling real-time trajectory computation with longer planning horizons in this preliminary example.
Cooperative pot transfer
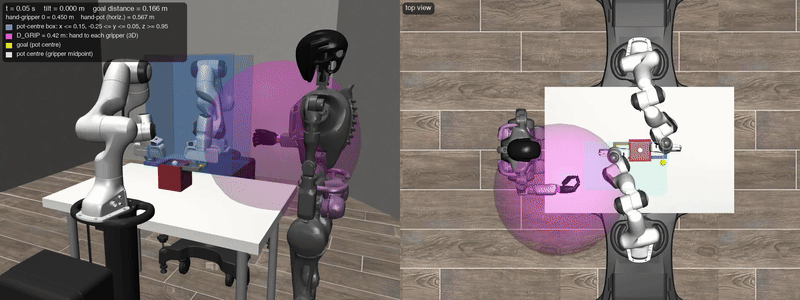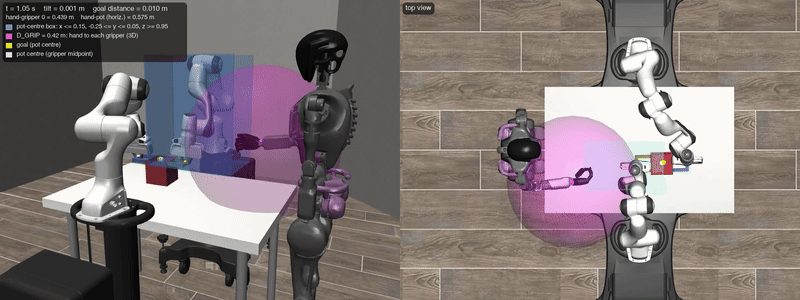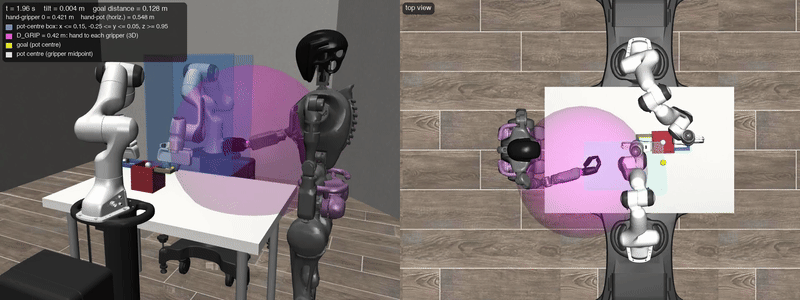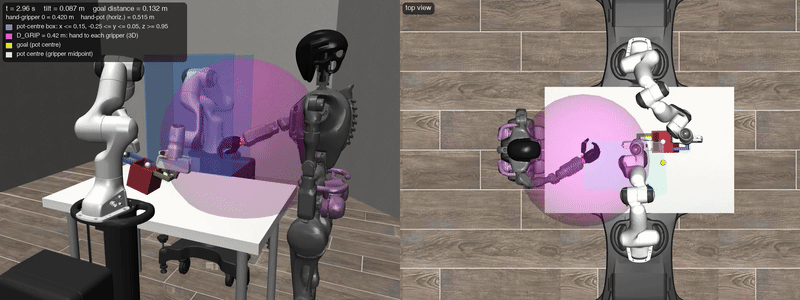
In this simulation, two robot arms cooperate to transfer a pot while keeping it balanced and maintaining clearance from an adversarial robot’s hand. The adversary tries to obstruct the transfer, so the cooperating arms must anticipate and respond to its motion.
Games of Ordered Preference
The problem
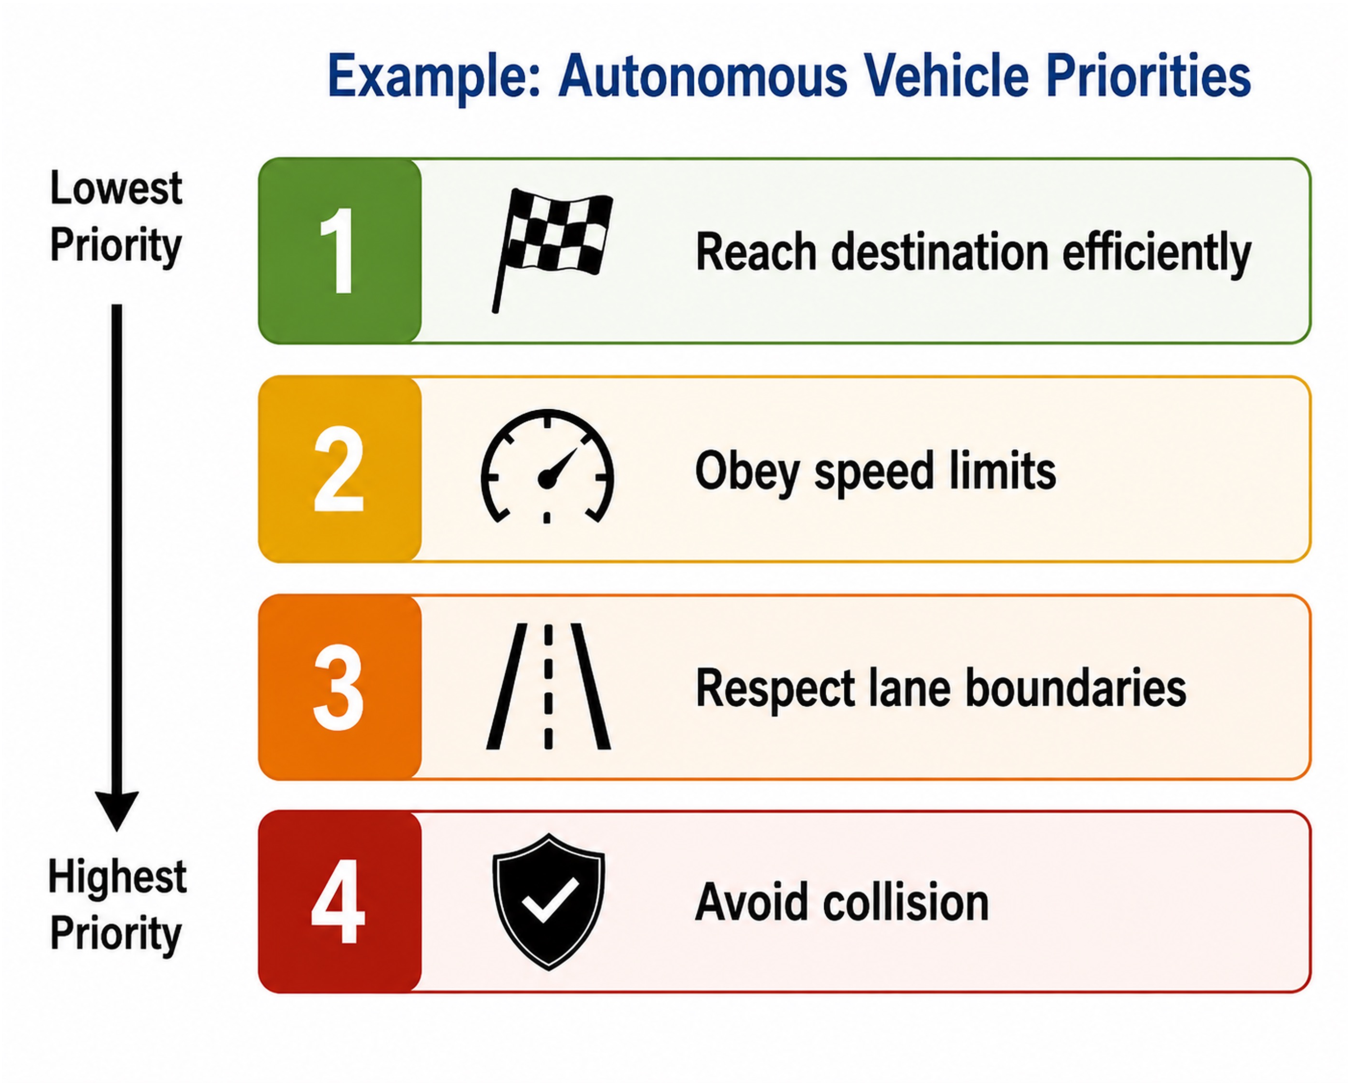
A robot may need to prioritize collision avoidance over progress, or task completion over energy efficiency. In a multi-agent setting, the outcome also depends on what other robots do. The question is how to compute decisions that respect each agent’s objective hierarchy while accounting for strategic interaction.
The solution
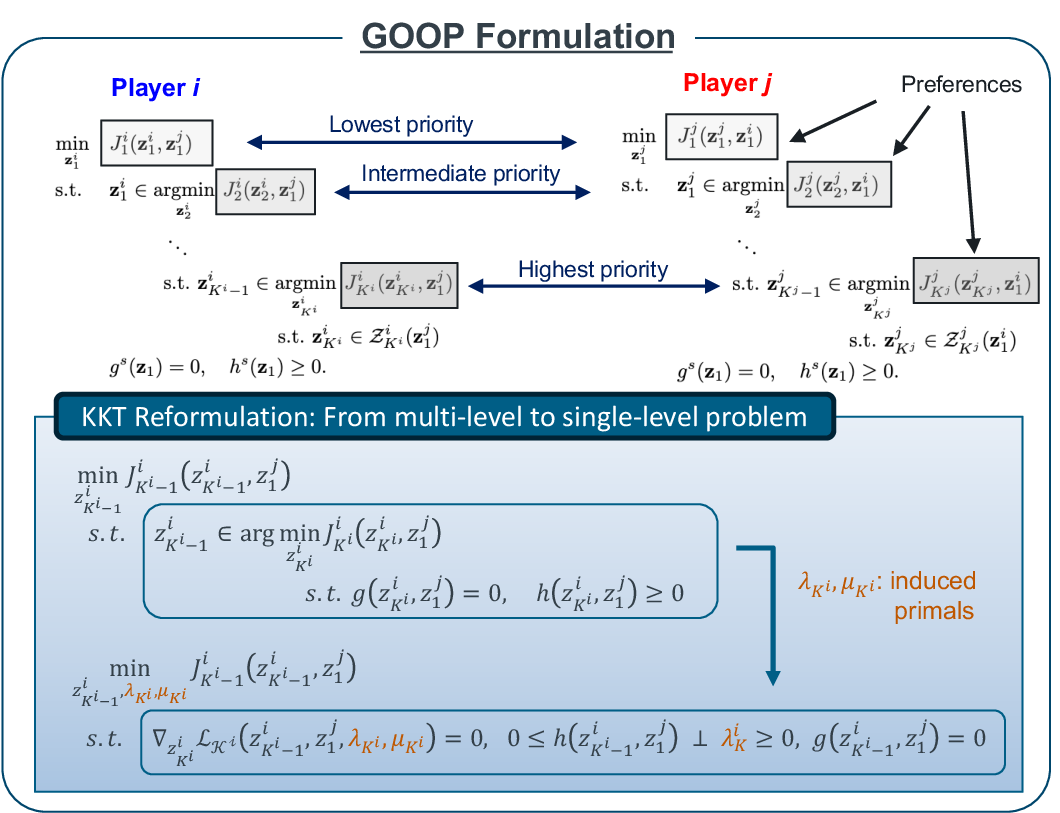
We developed Games of Ordered Preference (GOOP), a mathematical framework that models noncooperative games with strictly ordered preferences. We derived optimality conditions and solved a sequence of relaxed mixed complementarity problems to compute equilibrium candidates.
The original formulation can require exponentially many variables and constraints. In follow-on work, our team derived a reduced KKT system whose size grows polynomially, eliminating unnecessary variables and constraints. For quadratic objectives with linear constraints, the reduced and complete systems have the same primal solution sets; in general nonlinear problems, additional conditions are needed to certify equilibrium candidates.
The reported benchmark showed up to 10× speedup from the formulation change alone. The ongoing work above builds on the reformulation with a Newton solver for real-time receding-horizon control.
Relevance to robotics
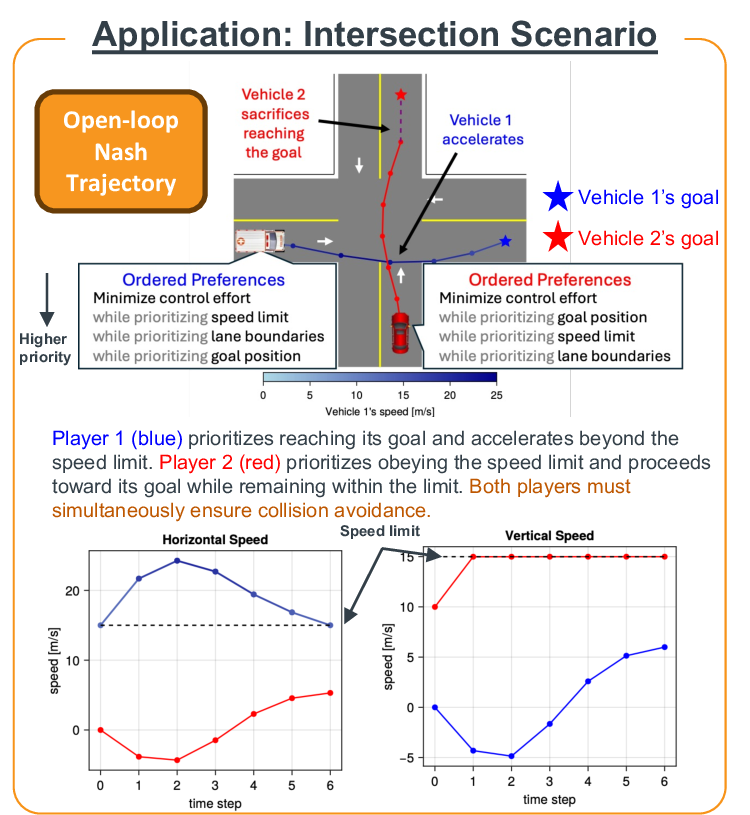
GOOP lets each agent express which objectives take priority when planning around others. The intersection example illustrates how different priorities can lead to different driving behavior.
- Paper · Code
- Preprint · Code — under review at SIAM Journal on Optimization.
- Related collaborative work: Approximate Solutions to Games of Ordered Preference, ITSC 2025.
Mixed-hierarchy games for robot interaction
Multi-robot systems can mix simultaneous decisions with leader–follower relationships. I co-developed methods for mixed Nash/Stackelberg games, using quasi-policy approximations to make their optimality conditions computationally manageable.
The team evaluated the solver in simulation and in a receding-horizon experiment with two Clearpath Jackals and an NVIDIA JetRacer. Paper · Code
Game-theoretic hierarchical routing
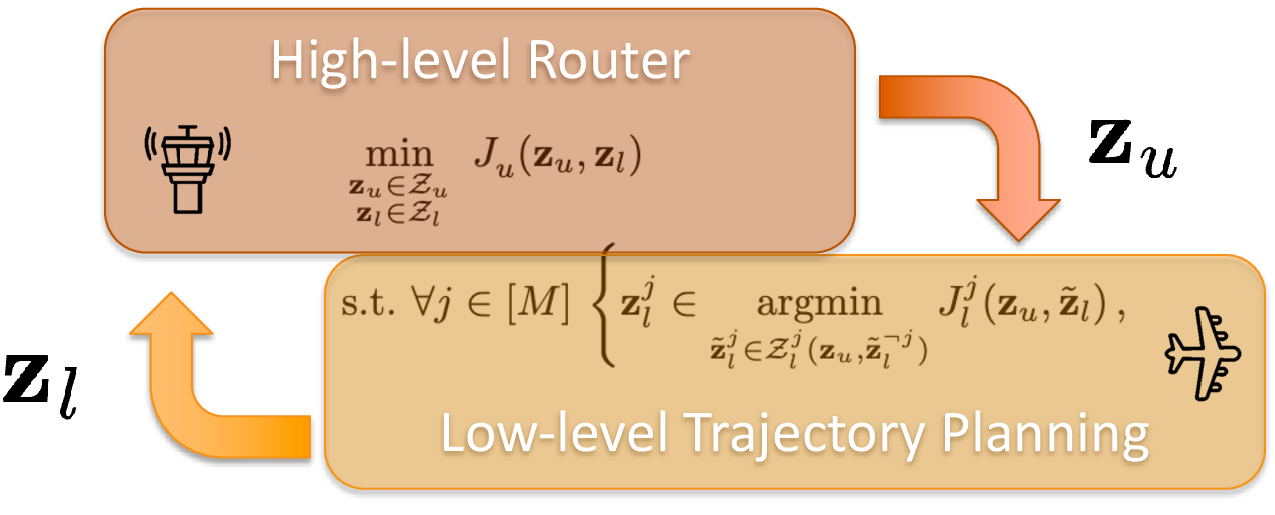
A high-level planner assigns routes, while individual vehicles optimize their own behavior along those routes. I developed a convex reformulation and a customized branch-and-bound method for this bilevel routing problem. The method finds a globally optimal solution for the modeled problem while accounting for strategic interactions among vehicles. Paper
Learning to replan multi-UAV routes
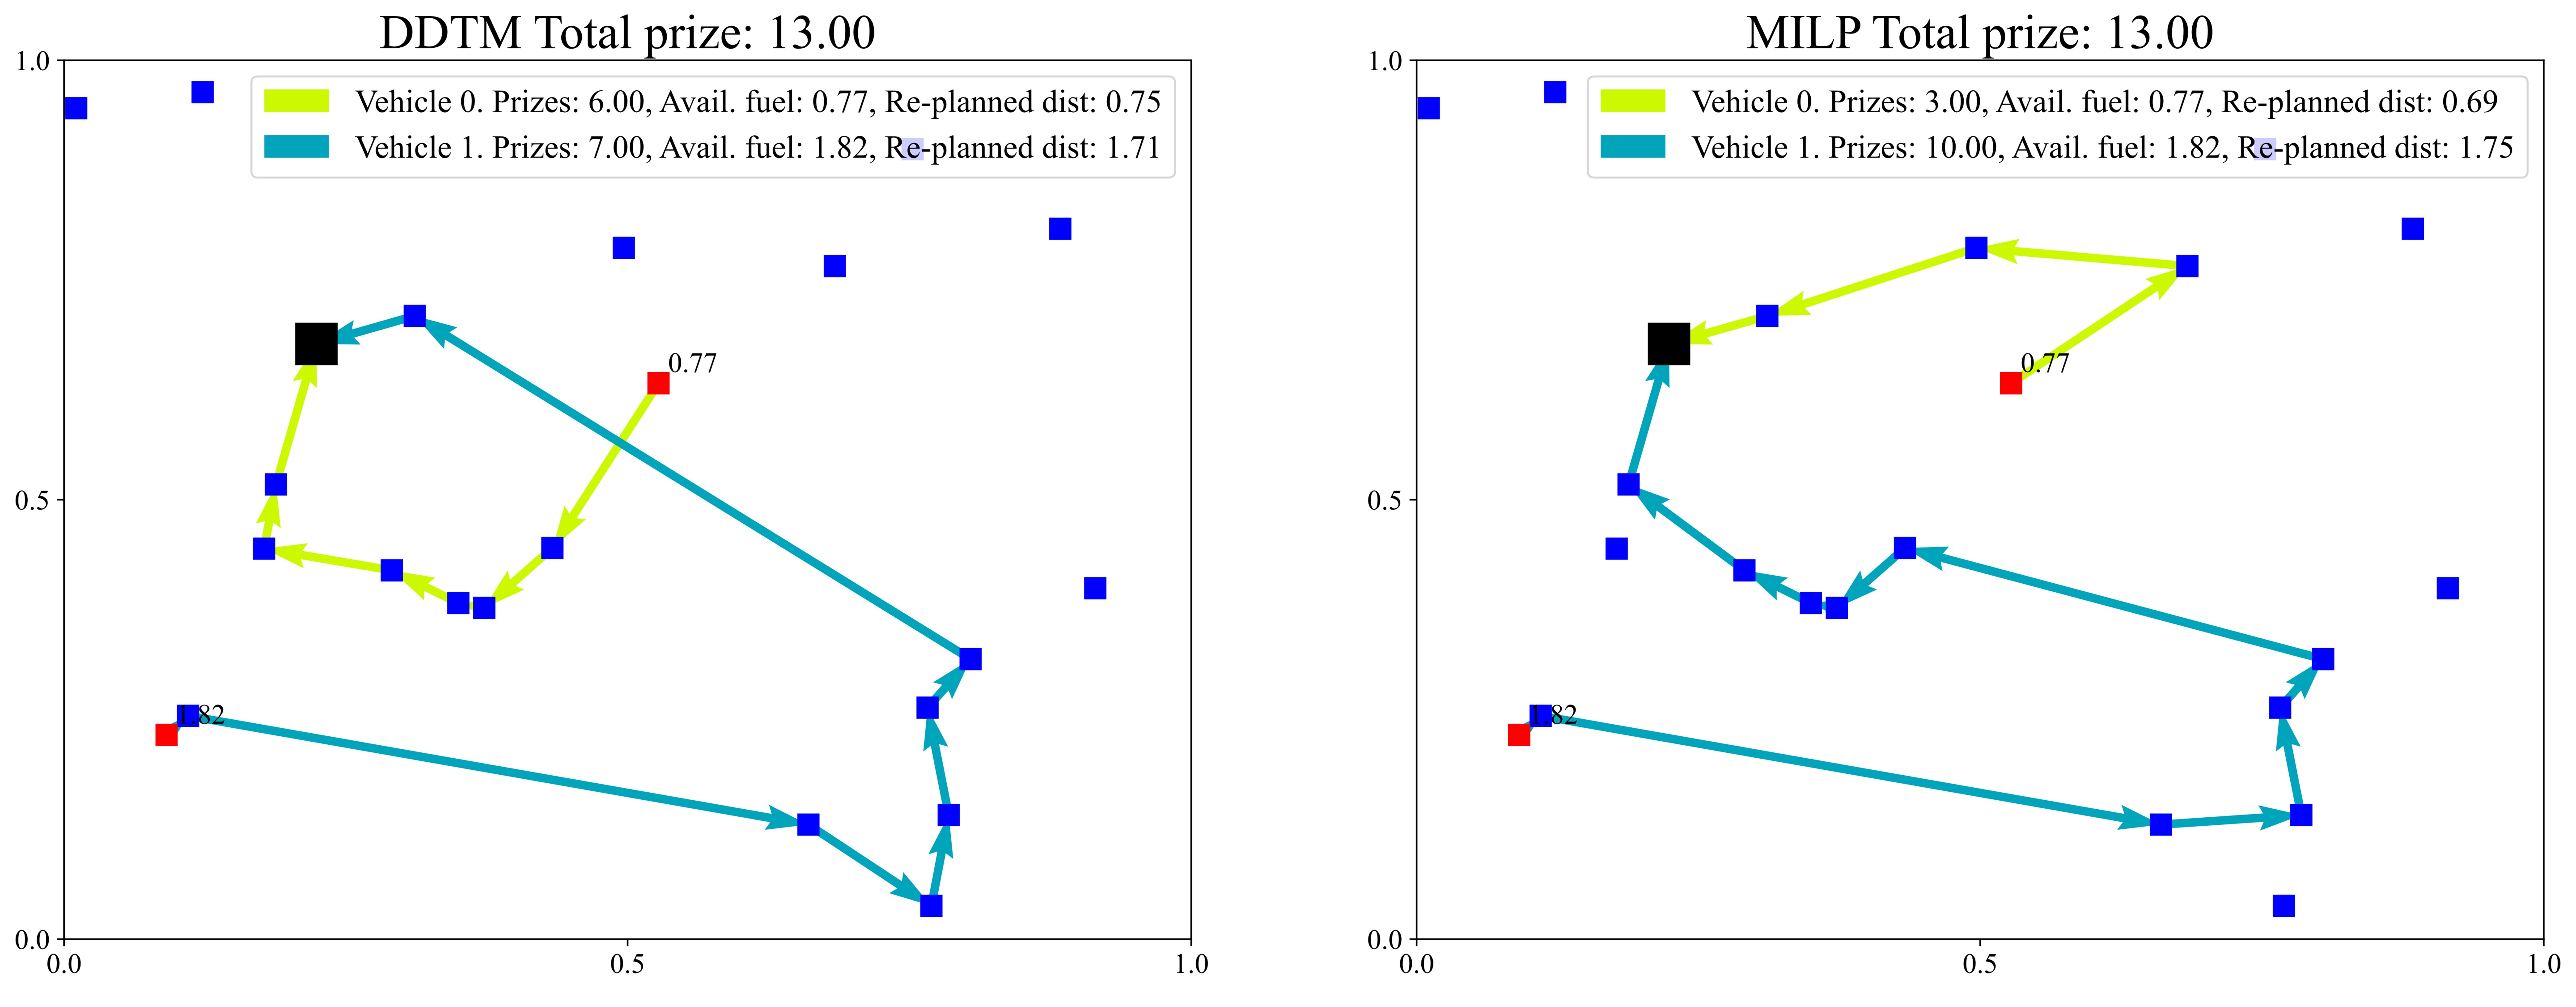
When a mission changes, vehicles may be far from the depot and have different remaining fuel or time budgets. I built a Transformer-based reinforcement learning policy for this multi-start team orienteering problem and developed a data-efficient training method.
The policy selects routes under resource constraints, and the training approach was also evaluated on traveling salesperson and capacitated vehicle routing problems. Paper · Paper · Code
Information gathering in noncooperative games
How should an agent allocate resources to learn about another agent’s objectives before interacting with it? I contributed to a two-stage game-theoretic framework and a gradient-based solution method for smooth information gathering. Paper · Code
Earlier research and engineering
Deep learning for aerodynamic prediction
At KAIST, I developed a residual neural-network pipeline to predict changes in aerodynamic coefficients as a vehicle’s shape changes under extreme flow conditions. The work involved preprocessing simulation data, training the model, and evaluating prediction performance. Paper · Paper
Trajectory optimization with waypoint constraints
For a KAIST optimal-control course project (2021), I formulated a waypoint-constrained trajectory problem using Hermite–Simpson direct collocation. I implemented an interior-point barrier method and compared its results with MATLAB’s fmincon.
Code · Project slides (PDF)
Multi-UAV mission planning
As a Research Officer at ADD (2017–2020), I developed mixed-integer and genetic-algorithm approaches for mission allocation and replanning, and implemented planning software for a Linux-based UAV simulator. This work led to a registered patent, KR102063851 (2020).
Self-configuring modular drone
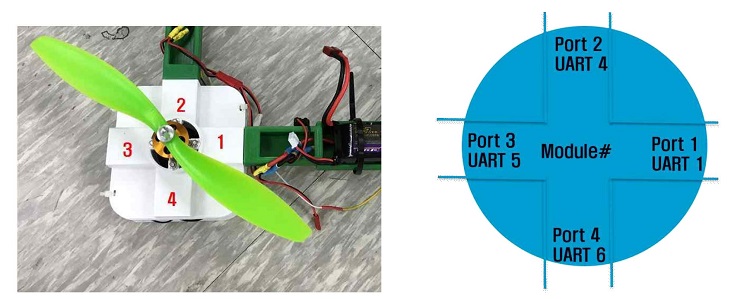
As an undergraduate research intern at KAIST (2015–2016), I designed and constructed a 3D-printable modular drone. The modules communicate to identify their arrangement before coordinated flight. The project received an Excellent Research Award in the Undergraduate Research Participation program. Flight demonstration (MP4) · Research poster (PDF)